BER confidence levels: time, bits, and errors
Connect specified BER, bit rate, duration, and measured errors to statistical confidence, then plan an interpretable BERT test.
Written and technically reviewed byElectroDesignForge Engineering Team
View the editorial processKey point: a measured BER is not enough to qualify a digital link. The result must be paired with the number of transmitted bits and a confidence level. A long error-free run provides stronger evidence than a short one, but it never proves that the true BER is exactly zero.
Quick reference
| Quantity | Relation | Meaning |
|---|---|---|
| Transmitted bits | N = BPS × T | statistical exposure of the test |
| Expected errors at the limit | λ = N × BERS | mean error count if the true BER equals the specification |
| Observed BER | BERobs = E / N | point estimate from the measured errors |
| Confidence | CL = 1 − FPoisson(E; λ) | evidence that the true BER is better than BERS |
| Zero-error shortcut | CL = 1 − exp(−N × BERS) | valid when E = 0 |
BPS is the transmitted bit rate in bit/s, T is the active measurement time in seconds, BERS is the specified BER limit, and E is the number of measured bit errors.
What the confidence statement means
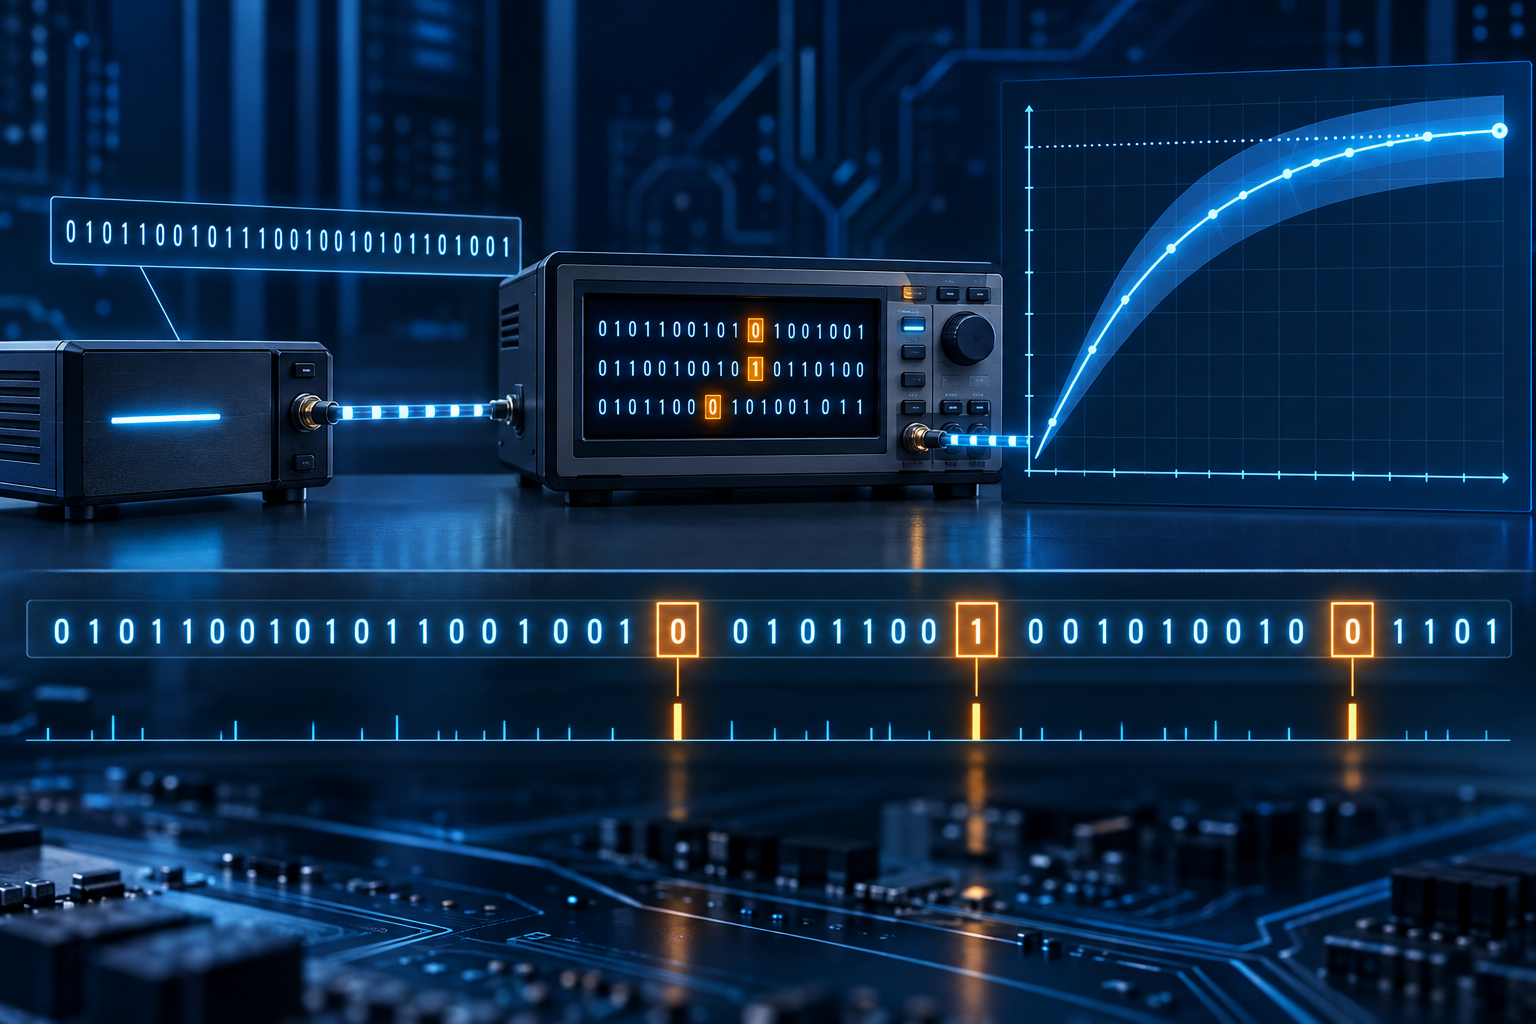
Assume the link really operates at the specified limit BERS. Over N transmitted bits, it would then produce an expected count λ = N × BERS. The calculator asks how likely that limiting link would be to produce more than the observed count E.
CL = 1 − P(X ≤ E | λ)
A confidence of 95% means that a link operating exactly at the specified BER would have only a 5% chance of producing E errors or fewer during the same exposure. The result therefore supports a one-sided statement: the tested BER is better than the specified limit at the displayed confidence, provided the statistical assumptions hold.
This is not the probability that the device is “good,” nor a guarantee about every future operating condition. It is a frequentist test result tied to the observed exposure and model.
Why the Poisson model is used
Each transmitted bit can be viewed as a Bernoulli trial. The exact error count is binomial:
X ~ Binomial(N, BER)
BER qualification normally combines a very large N with a very small probability per bit. In that rare-event regime, the binomial count is accurately approximated by a Poisson distribution with mean λ = N × BER. Its cumulative probability is:
P(X ≤ E | λ) = exp(−λ) × Σ[k=0…E] λ^k / k!
The calculator evaluates the equivalent regularized incomplete-gamma function for numerical stability, especially when λ or E is large.
Zero measured errors
For E = 0, the equation becomes particularly simple:
CL = 1 − exp(−N × BERS)
Solving for the required number of bits at a target confidence gives:
Nrequired = −ln(1 − CLtarget) / BERS
Trequired = Nrequired / BPS
At 95% confidence, −ln(0.05) ≈ 2.996. An error-free test therefore needs about 3 / BERS transmitted bits. At 99% confidence, the factor rises to about 4.605; at 99.9%, it is about 6.908.
Worked example
Test a 1 Gbit/s link for 2 hours against BERS = 1 × 10⁻¹², with zero measured errors:
N = 1 × 10⁹ × (2 × 3600) = 7.2 × 10¹² bits
λ = 7.2 × 10¹² × 1 × 10⁻¹² = 7.2
CL = 1 − exp(−7.2) ≈ 99.925%
The observed BER is 0 / N = 0, but the defensible conclusion is not “BER equals zero.” It is that the measured result supports BER < 10⁻¹² at approximately 99.925% confidence under the stated assumptions.
When errors are observed
An observed error does not automatically fail a BER objective. It reduces the confidence for the same bit count because a link operating at the limit is less surprising when it also produces one or more errors.
For the previous example with E = 1:
CL = 1 − exp(−7.2) × (1 + 7.2) ≈ 99.39%
For a fixed target confidence, every additional observed error increases the required bit count and test duration. Use the graph in the BER Confidence-level Calculator to compare these curves.
Planning a credible BER test
- Define the BER limit and confidence before starting the test.
- Use the actual payload bit rate seen by the detector, not a symbol rate or nominal lane aggregate unless they are equivalent.
- Count only time during which the pattern generator, receiver, and error detector are synchronised and valid.
- Record every loss of synchronisation, reset, retune, temperature change, and interruption.
- Exercise relevant patterns, voltage, temperature, channel loss, clock conditions, and lane configurations.
- Report
BERS, confidence,N,E, bit rate, active duration, pattern, and test conditions together.
ITU-T O.150 describes reproducible pseudo-random test patterns and synchronisation considerations for digital transmission measurements. Pattern choice matters because deterministic or traffic-dependent failure modes may not be exercised equally by every sequence.
Assumptions and limits
The calculation assumes:
- errors are independent rare events;
- BER remains constant throughout the measurement;
- every transmitted bit has the same error probability;
- the detector counts errors correctly and does not silently lose synchronisation;
- the tested conditions represent the claim being made.
These assumptions can fail with burst errors, crosstalk patterns, equaliser adaptation, thermal drift, intermittent connectors, EMI events, clock slips, forward-error correction, or error-detector dead time. A single Poisson confidence number then understates the structure in the data. Preserve time-stamped error logs and analyse burst length, inter-arrival time, and operating-condition dependence.
For FEC links, distinguish raw/pre-FEC BER from post-FEC BER and uncorrectable block rate. A decoder transforms the statistics; do not apply a raw independent-bit model to post-FEC outcomes without a justified model.
Common pitfalls
- Reporting only
E/Nwithout the confidence or total bit count. - Treating zero measured errors as proof of zero BER.
- Mixing seconds, minutes, and hours when calculating
N. - Using baud or symbol rate when each symbol carries multiple bits.
- Including time when the tester was unlocked or the pattern was invalid.
- Restarting after an error and reporting only the clean segment.
- Ignoring parallel lanes: state whether
NandEare per lane or aggregated. - Assuming a random-error model covers deterministic jitter and pattern sensitivity.
Sources
- NIST/SEMATECH e-Handbook — Poisson distribution, probability mass and cumulative distribution functions.
- NIST/SEMATECH e-Handbook — Poisson approximation to the binomial, rare-event count modelling.
- ITU-T Recommendation O.150, digital test patterns and synchronisation for performance measurements on digital transmission equipment.